Fully Managed AnythingLLM
as a Service
Deploy AnythingLLM as a fully managed service starting at €9/mo. Get automated backups, SSL, updates, support and monitoring included.
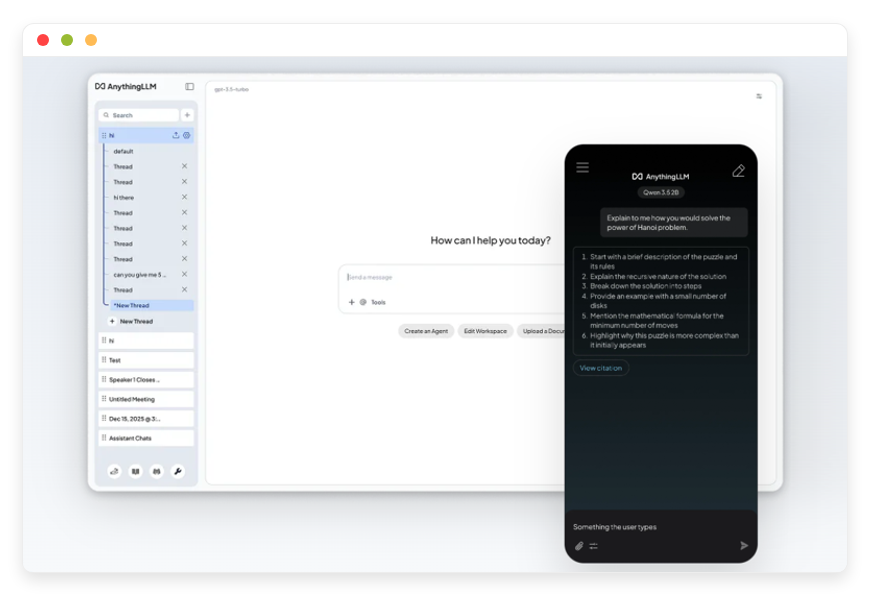
AnythingLLM is an open-source private AI application, workspaces, retrieval over your own files and in-workspace agents, combining the convenience of a hosted assistant with the control of software that runs on infrastructure you chose.
✓Free 7-day trial ✓99.9% Uptime SLA ✓No credit card ✓Cancel anytime
✓Free 7-day trial ✓99.9% Uptime SLA
✓No credit card ✓Cancel anytime

AnythingLLM
STARTING AT
USAGE
 Germany
 Finland
 Netherlands
 UK
 Sweden
 United States
 Canada
 Singapore
 Japan
 Australia
 Brazil
 South Africa+9 more →
ABOUT THE SOFTWARE
What is AnythingLLM
FEATURES
What AnythingLLM does
WHAT'S ALWAYS INCLUDED
Every app. Fully managed.
Nothing extra to pay for.
Every app on DANIAN ships with the same operational baseline. You do not choose a backup add-on or a monitoring tier. Hosting, patching, backups, SSL, and support are part of the €9, and they apply to AnythingLLM the same way they apply to everything else in the catalog.
WHY MANAGED
Why teams pick managed AnythingLLM
REVIEWS
Hear from customers like you
No more maintenance headaches!
Finally, I can relax and not bother with maintenance. Each of the softwares that we run on DANIAN is automated and running stable for couple months already. They even assist us with modifying the DNS records. Once we needed to modify the config of Nextcloud so that we are able to upload higher than 5GB files and they assisted us fast. I also love their documentation!

Kevin Blackwell
Best managed service
I previously ran Peertube, Mastodon, Mattermost and Mirotalk on other providers before switching to DANIAN. I was tired of handling the updates and backups myself. Not only that the performance is "out of this world" fast, but their tech support is amazing. Since then I added 5-10 more Apps on my account. I also love how they add more softwares on their list constantly!

William Northfield
Love the personalized service!

George Adams
n8n runs excellent

David Hartmann
Smooth experience
I needed a way to manage the projects and files for my company. This was the first time I learn about opensource. I asked their support team and they assisted me immediately. I started with Openproject. Later I added Nextcloud. My team were able to get used to the apps fast.

Levi Nilsson

Bye GA

Wyatt Mitchell
Love the freedom
I wanted to use a crm for my startup. I signed up for the free trial. Tried out espocrm and dolibar and picked one. Their dashboard is very easy for a beginner. I recommend them and feel confident in choosing them.

Elias Koch
Wow just wow
After discovering DANIAN, I wished I'd found them sooner — their solution is excellent and deserves wider recognition. Very good solution!

Tyler Hollander
Professional tech support!

Bastian Engel
Their support team is the best!
I had a problem with my card and the subscription could not be renewed in time. I notified their support and surprisingly, they showed much understanding. They basically left my apps run until I solved the card issue. Other providers would have deleted my data in a heartbeat. This is the way to build client-vendor trust!
George Adams
Fair price and fast
4 months ago I activated n8n, Uptime kuma, Vaultwarden and Paperlessngx. So far everything is perfect. The performance of all apps is excellent. I contacted their support team couple times for using custom subdomains for the apps and they were fast and kind. I'm constantly recommending them to my network!

Atanas
Vaultwarden 10/10
I wanted to selfhost a passwords manager for my company but I didn't trust the mainstream providers. I tried out Vaultwarden for the free trial. I loved how their support team communicated with me professionally but still kind. I know that I can contact them whenever with whatever question I have. Recommended!

James Smith
Multiple locations options

Edward Nelson
Everything just works!
My focus is on my business, not running servers. I love that I can lauch any app without having to think about the tech behind it. Everything just works!

Tony Roy
Awesome support team!

Filip
Very proactive!
Today couple of the videos on my Peertube got viral. Before I even noticed, their support have notified me via email that they proactively upgraded my app with more cpu & ram so that it continues to work without any downtime. They left the upgraded app with the added resources for couple days until the traffic stabilizes. After that I had the possiblity to stay on the same plan or keep the upgraded plan. Out of gratitude I stayed on the upgraded one.

Luke Hall
Win-win!
I run a web design biz. After I perform the work for my clients, they constantly ask me for more software solutions. So I partnered with DANIAN. Not only I provide the requested softwares for my clients and get the increased revenue boost by delegating all to DANIAN, but also for those clients that wish to order directly from DANIAN, I send them an affiliate link. Win-win on all sides!

Luke Walker

Jeffrey Johnson
Awesome customer service
I needed to add analytics on my website but I didn't know anything about DNS. Their team guided me at all phases and they performed the changes for me. Additionally they were transparent and notified me of every change applied and steps performed.

Gabriele Marino
Good admin dashboard
Not only that I got Chatwoot, I also have access to the management dashboard. I love that I can view my hourly/daily usage and perform manual backups and restorations if needed. I don't need the level of control but it feels good to know that I have it if I need it.

Matthew Turner

Andreas Schmitt
Great service!
I configure custom Matomo tracking for my clients as a monthly service. Many of my clients were asking if they can selfhost Matomo instead of using the Cloud service. My employee recommended DANIAN. Basically, I can activate as much Matomo's in any of 20+ countries the same day. Additionally the affiliate revenue is a nice bonus.

Jacob Turner
Smooth experience
I was listing through youtube tuts on how to install Bookstack myself. Then randomly, I found their video playlist exactly for Bookstack. Got curious and went at their website. For the same price (or higher) that I would pay for just the VPS, with them I'm getting a fully managed Bookstack. It's a no-brainer decision!

Elias Gustafsson

Mason Hayes
Its a great service
Its a great service. I love the performance of my Mastodon community. It keeps on growing and I don't have any worries about backups, secuirity, updates, etc.

Vinícius Rocha
Very intuitive solution!
I wanted to use a nocode software for my company. A friend recommended them so I tried both Baserow and NocoDB, couple days later picked one.

Haruto Hashimoto

Henrik Otto
USE CASES
Three teams who run AnythingLLM on DANIAN
The shape of an AnythingLLM deployment follows the corpus, not the headcount. These three patterns cover most of what teams bring to us: client work split by engagement, internal operational knowledge, and a research corpus that must stay on one instance.
12-PERSON CONSULTING FIRM
One workspace per client engagement
Proposals, deliverables and interview notes are loaded into a workspace per engagement, so a question about one client cannot retrieve another client's material. The instance runs in the region closest to the client base and connects to a hosted model provider the firm already contracts with.
40-SEAT SUPPORT AND IT TEAM
Runbooks and ticket history behind one assistant
Runbooks, wiki exports and resolved-ticket text feed a single workspace. The three-role model gives first-line staff chat access only, while the widget is embedded on the internal portal with an origin allowlist so it answers there and nowhere else.
9-PERSON RESEARCH GROUP
Papers and protocols against a self-hosted model
The group loads papers and protocol documents, keeps the on-instance vector store, and points the model connection at their own inference endpoint rather than a public API, so no document text leaves the instance at query time. One workspace per project.
COMPARISON
Four ways to run AnythingLLM
Four paths lead to a private assistant over your own documents. Three of them scale with headcount or with your own time. The comparison below holds the workload constant and changes only who runs the software and what it costs at one, five and ten users.
| Path | 1 user | 5 users | 10 users | What you still own |
|---|---|---|---|---|
| Proprietary SaaS: ChatGPT Business | $40/mo | $100/mo | $200/mo | Nothing to run, and nothing to decide. Two-seat minimum, per-seat billing, monthly rates higher than annual, and agent usage capped per user per month. |
| Self-host on a VPS | $24/mo | $24/mo | $24/mo | The whole stack. A production-class VPS at roughly $24/mo plus your model spend, plus patching, TLS renewal, proxy configuration, backup verification and the embedder decision. |
| Home server | ~$900 once | ~$900 once | ~$900 once | Hardware and power. An HP ProLiant ML30 Gen10 class tower plus electricity, your own uplink, your own redundancy, and no off-site copy unless you build one. |
| DANIAN managed AnythingLLM | €9/mo | €9/mo | €9/mo | The documents and the model choice. Flat price regardless of how many people use the instance, with updates, backups, monitoring, TLS and support included. |
Seat prices reflect published list rates for the proprietary path and exclude what you pay your model provider on any of the four. On the managed path the €9 does not change with user count, because it is priced per app rather than per person.
BY INDUSTRY
AnythingLLM for specific industries
Three sectors put unusual demands on a document assistant, because the underlying records carry a retention duty and a control requirement. In each case the configuration decision is made before ingestion, since the embedder and vector store cannot be changed later without re-embedding.
FAQ
Frequently asked questions
Three groups of questions. The first covers how AnythingLLM is configured on our platform, the second covers getting your existing setup and documents onto it, and the third covers billing, support and the platform rules that apply to every app we run.
01
Technical and configuration
02
Migration and onboarding
03
Billing, support, and platform
DEPLOY IN YOUR REGION
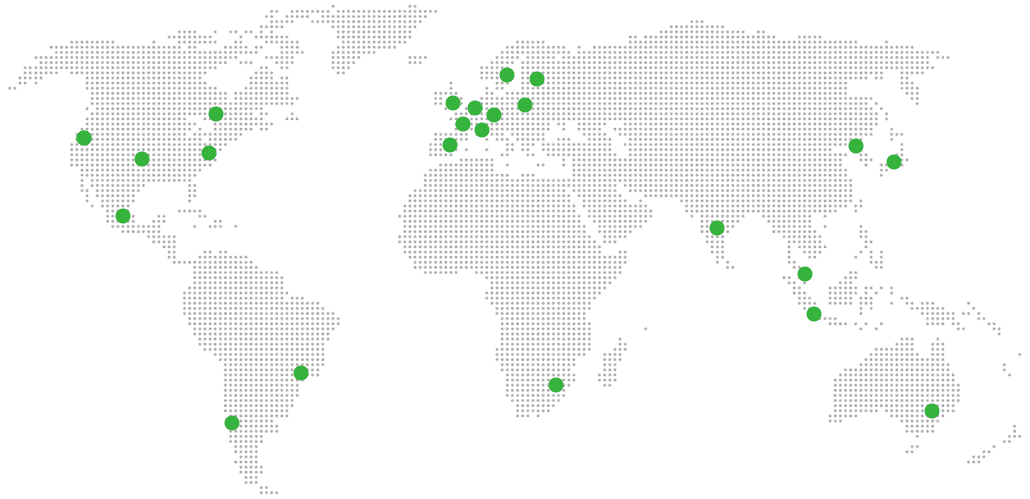
21 datacenter locations on six continents
Pick the region closest to your users.
United States, Germany, Finland, Singapore, Australia, Brazil, Canada, Netherlands, UK, Spain, Italy, France, Sweden, Malaysia, India, Japan, Mexico, Poland, South Korea, Chile, South Africa and more coming soon
Try managed AnythingLLM for 7 days
SERVICES
COMPANY
RESOURCES
COMPARE


